AI study help
AI study help for the Digital SAT — a mock debrief and highlight-to-explain
A written debrief after each mock, and one-sentence explanations. Never during an exam.
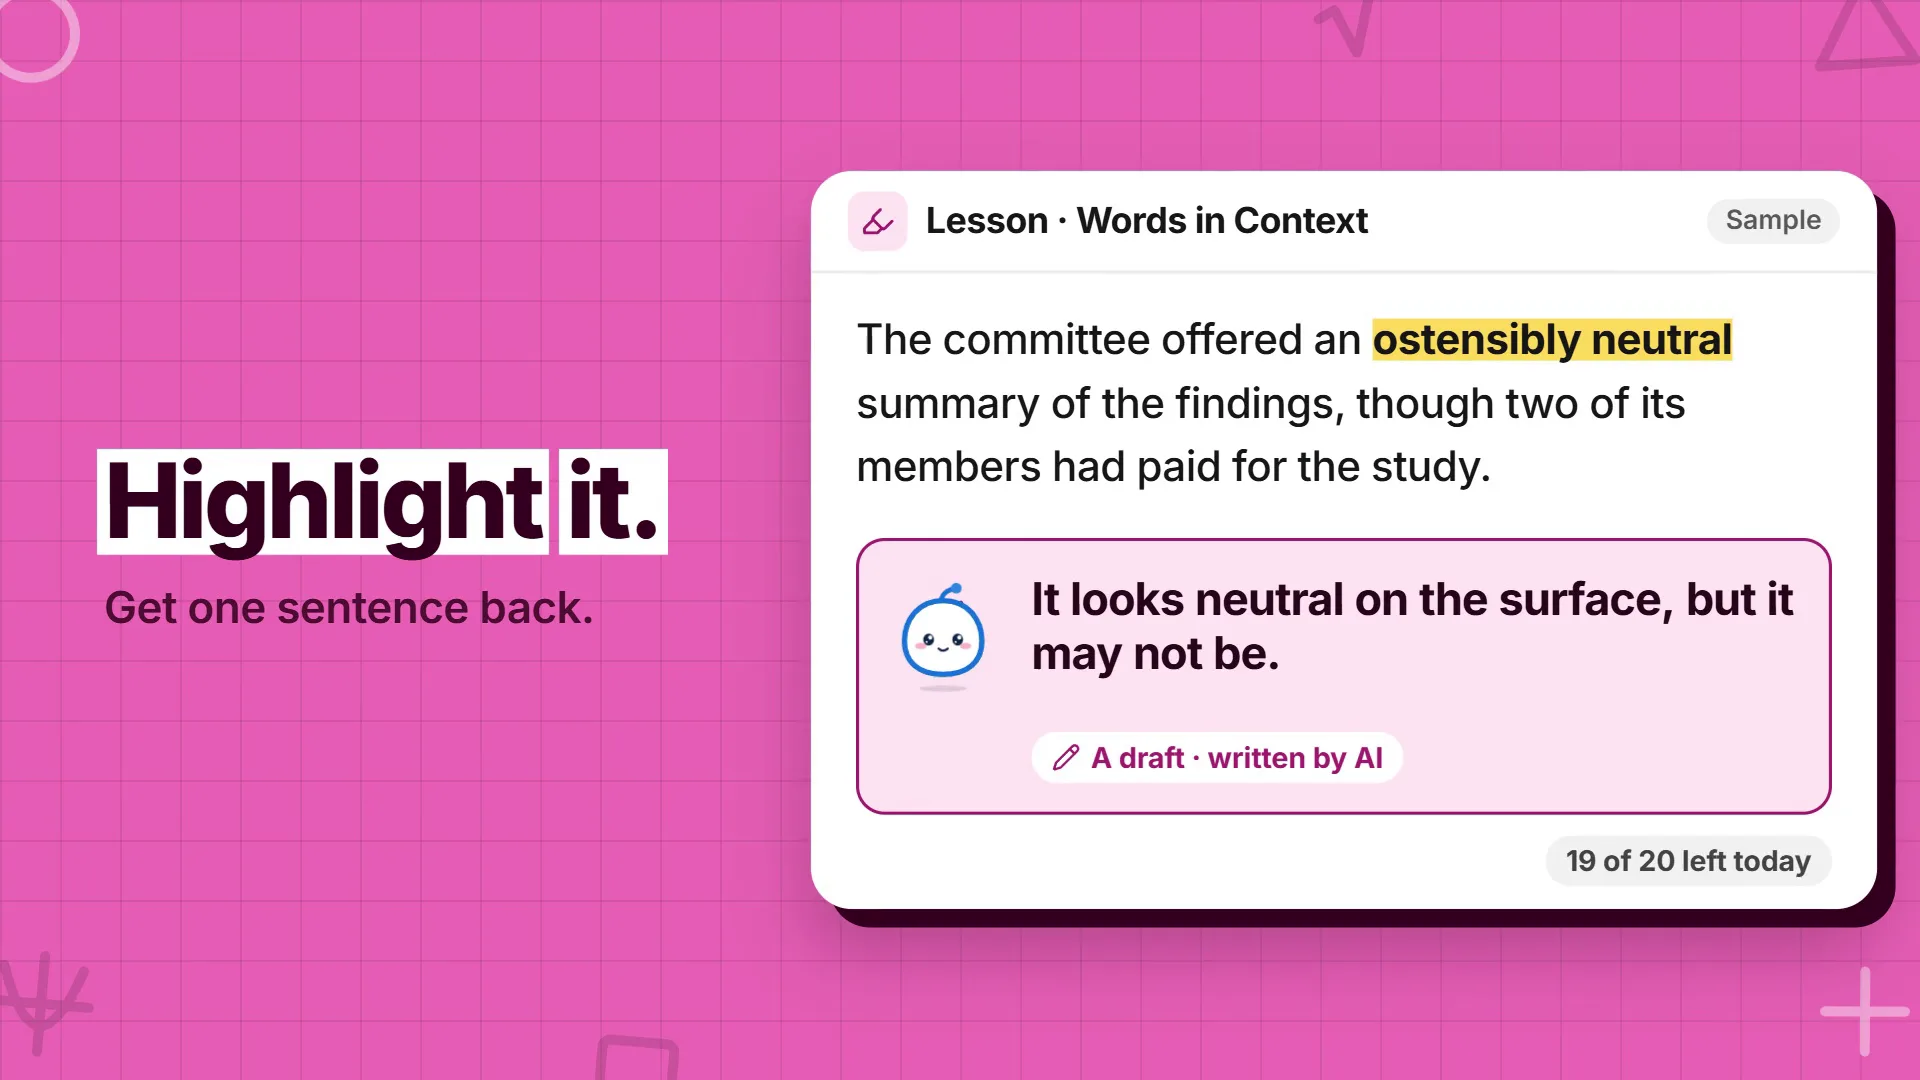
Two things today. After you submit a mock, the wording of your debrief is drafted by an AI model from numbers our software has already calculated. And in a lesson, a drill or a post-exam review you can select any phrase and get a single sentence explaining it. Neither is available inside a timed sitting — not as a setting that could be switched, but because three things the product has already published forbid it.


- A written debrief on each mock's results page — wording by AI, every figure from your own results
- Highlight any phrase in a lesson, drill or review for a one-sentence explanation
- Explains what a phrase means — it will not answer the question for you
- Nothing about who you are is sent, and nothing you highlight is stored
- Only providers that keep nothing — never DeepSeek's own service
- 20 explanations a day and 60 a week; 6 debriefs a day and 20 a week
- Structurally absent from the exam runner, which does not import it
- Ask why an answer is wrong, in context of your own attempt
- Grounded in the track's own verified material, with citations
- A study conversation that can see your weakest skills
Where this actually stands
Partly live. The mock debrief and highlight-to-explain both work today, on DeepSeek V4 Flash run by zero-data-retention hosts through OpenRouter — fast enough that an answer arrives before you have finished re-reading the sentence — with a hard per-account budget consumed before any request leaves. The larger tutor, one that can see your attempts and cite the explanations already written for your track, is not built. The search index it will need exists; the tutor is deliberately later than the budget and privacy rules that have to hold it up.
What it does today
Select a phrase — up to 400 characters, a phrase rather than a page — and one sentence comes back explaining it. It is mounted in lessons, in drills, and in the review screen after a sitting is submitted.
It explains; it does not solve. If the thing you highlighted is itself a question, it will tell you what the question is asking rather than what the answer is. That is not a disclaimer, it is in the instructions the model is given, and it is the difference between a study aid and an answer key.
After a mock, the same model drafts the wording of your results debrief from a summary of numbers our software has already calculated. It writes placeholders, not figures; your figures are filled in from your own results, and a draft that states a number of its own is rejected.
The model is DeepSeek V4 Flash, chosen because it is fast. The whole value of a gloss is that it arrives while you are still looking at the phrase; a slower, better sentence would be worse, because you would have moved on before it landed.
Where requests go
Every request goes through OpenRouter and carries a zero-data-retention requirement, so only hosts that have committed not to store what we send, or train on it, can receive it. DeepSeek's own service is excluded by name. If no qualifying host is available, the request is not sent anywhere else: you get our standard wording.
A request never carries your name, email address or account. The explanation request contains the phrase you chose; the debrief request contains numbers and skill names.
Nothing is stored
The selection is sent, an answer comes back, and both are dropped. There is no table recording what you highlighted, no event carrying the text, and nothing echoed back in an error message.
The budget counter counts calls, not content. A version of this feature that logged what students found confusing would be genuinely more useful to us to have, and it is not what the privacy policy says, so it is not what was built.
Never during a timed exam
The exam runner does not import this feature. That is the mechanism — not a flag, not a permission check that a future change could get wrong.
Three separate published commitments require it. The honour code says no notes, no search, no help from anyone else, and specifically not looking things up mid-exam. The correctness invariant says the key is withheld until submission, and a model answering questions about a live item is a correctness oracle by inference even when no key field is in the payload. And the privacy policy says we never send the text you highlighted anywhere — so the one place that is allowed is where you asked for it, outside a ranked sitting, used once and discarded.
The cap, and why it is a hard number
Twenty explanations a day and sixty a week, and six debriefs a day and twenty a week, per account. The budget is consumed before the request leaves, and if the counter cannot be reached the call is refused rather than let through.
That direction is deliberate and it is the opposite of how the rest of the platform degrades: a failure to check the budget fails closed here, because the cost of letting an unmetered feature through is unbounded and the cost of a student not getting one gloss is one gloss.
The cap is also what stops this becoming a paywall later. A runtime AI feature with no ceiling has exactly two futures — it gets restricted to paying users, or it gets removed — and both of those are worse than a number stated up front.
Common questions
Will the AI assistant be available during a mock exam?
No. A ranked sitting has no help available in it, by design — an assistant inside a timed exam makes the score meaningless and the leaderboard dishonest. It will sit in review and study, after a module closes.
How many explanations do I get?
Twenty a day and sixty a week, per account. The budget is consumed before the request is sent, and if the counter cannot be reached the call is refused rather than let through — the one place on the platform that fails closed rather than degrading, because an unmetered AI feature has unbounded cost and a missed gloss costs one gloss.
Is what I highlight stored anywhere?
No. The selection is sent, an answer comes back, and both are dropped. There is no table for it, no event carrying the text, and the budget counter counts calls rather than content. A version that logged what students found confusing would be more useful to us and is not what the privacy policy says.
Does the AI decide my score or my study plan?
No. Scores, skill estimates, review timing and the order of your plan are calculated by our own software. The debrief's wording is drafted by AI with placeholders, and your figures are filled in from our calculations — a draft that states a number of its own is rejected. The How we use AI page shows exactly what is sent and kept.
Read next
- How should you read your practice test results?Read the domain breakdown before the score. The total tells you where you are; the breakdown tells you what to do on Monday. A 690 with one weak domain is about a week of work — a 690 that is evenly weak is closer to a month.
- What does a practice SAT score range actually mean?A score range is the platform admitting how much it does not know. The centre is its best estimate of your scaled score; the width is how far that estimate could be off given the evidence behind it. A single number from a practice test carries the same uncertainty — it just hides it.
The rest of a track
Each part is useful alone. Together they are the point.
- Available nowStudy plannerStop deciding what to study. Open the app and do today's mission.
- Available nowLessons and drillsTwo-minute lessons, then prove it immediately.
- Available nowAdaptive mock examsTwo modules per section, routed by how you did. Like the real thing.
- Available nowScore band and rankingA score range you can trust, not a number we made up.
- Available nowLeaderboards & seasonsHow ranking, percentiles and tiers work.
Missing something you need? Request it.